How to Fix “Crawled Currently Not Indexed” in GSC
The technical SEO experts at 20North break down the “crawled - currently not indexed” issue in GSC.
The Short Answer: "Crawled - Currently Not Indexed" means Google has found and crawled a page on your website but has decided not to add it to its search index yet. This means the page is not eligible to appear in Google search results or generate organic traffic. To fix it, improve the page's content quality, strengthen internal links, confirm there are no technical barriers, and make sure the page provides unique value that matches what users are searching for.
Visibility is the foundation of success online. Moving the needle on visibility means getting content crawled and added to Google's index, not just published. Often you will find that a page has been crawled by Google but still does not appear anywhere in search results. Google Search Console flags this as "Crawled - Currently Not Indexed," and it is one of the most common indexing issues our technical SEO team runs into.
What "Crawled - Currently Not Indexed" Actually Means
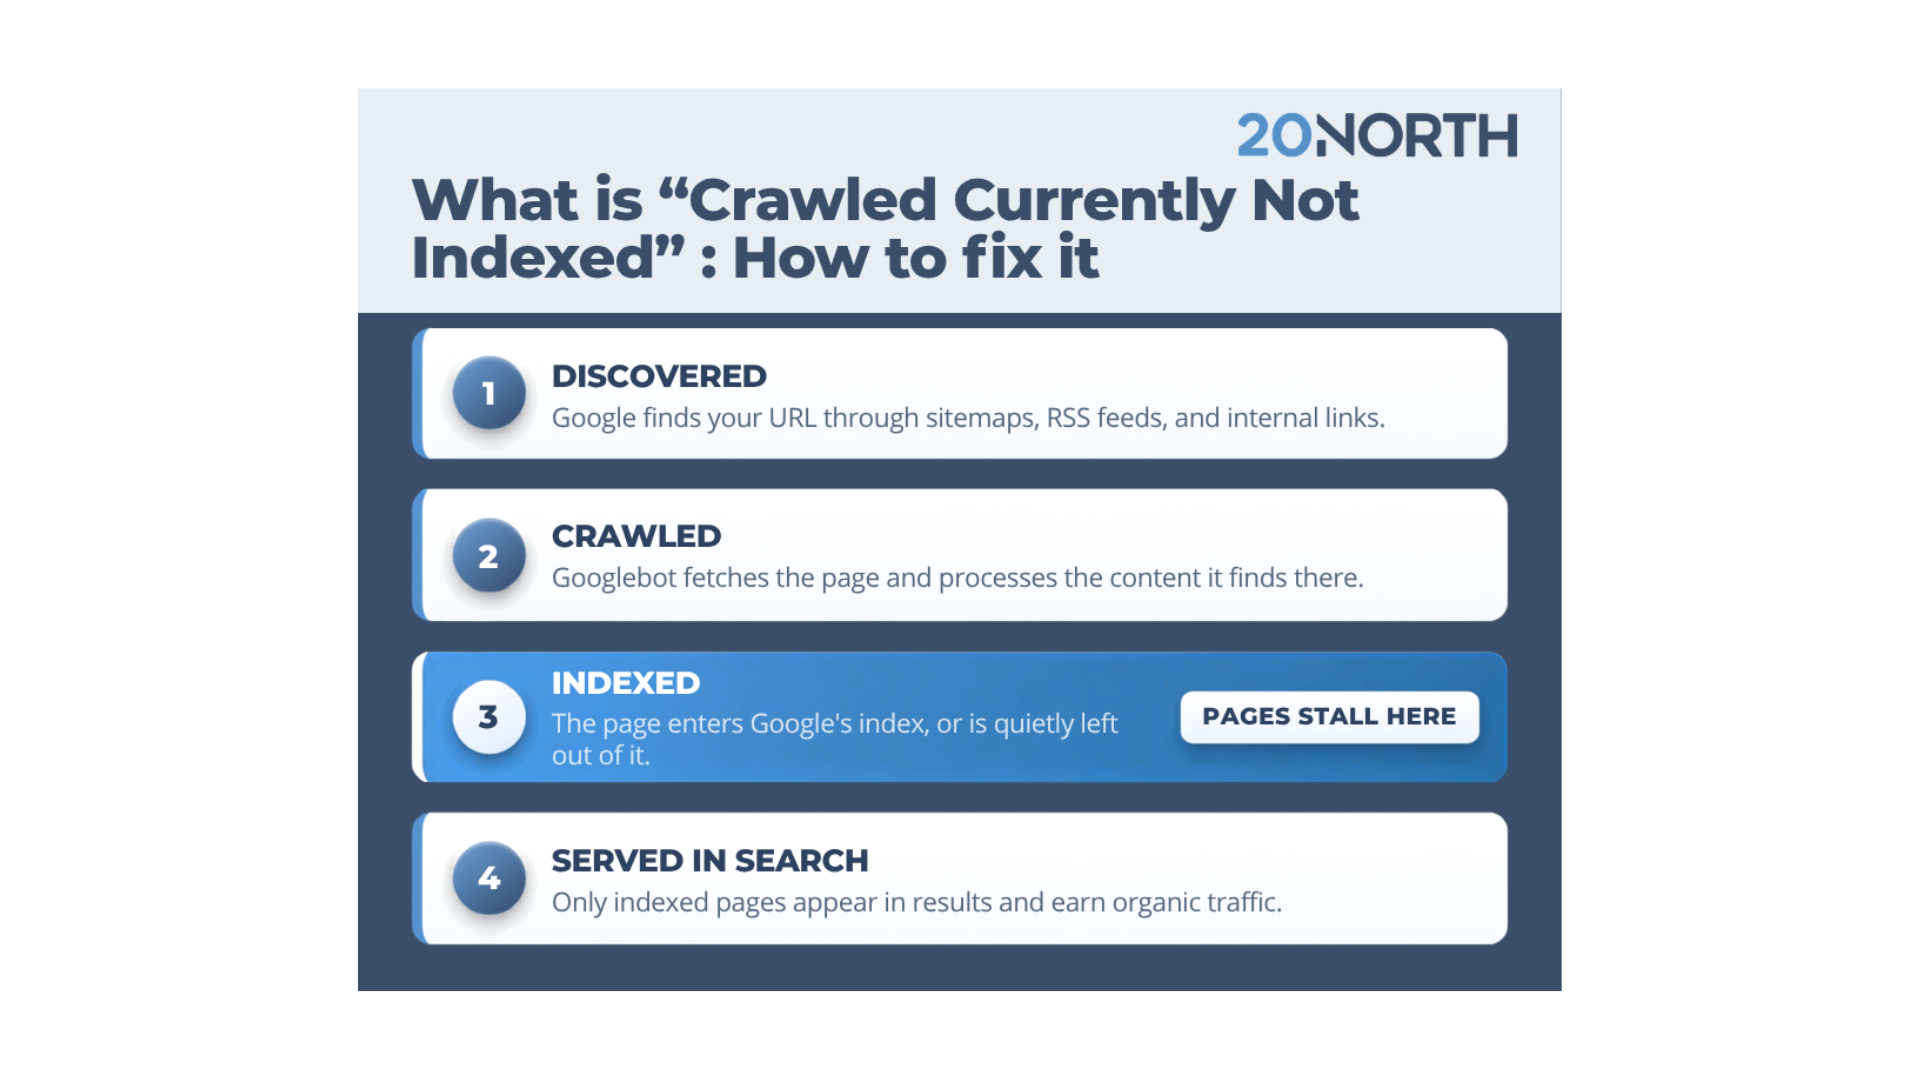
The "Crawled - Currently Not Indexed" status means Google has discovered and crawled a webpage but has decided not to add it to the search index yet. The page is known to Google and does not have a crawl error, but it will not appear in search results or generate organic traffic until it is indexed. According to Google's Page Indexing report documentation, the page may still be indexed later, and repeatedly requesting indexing for the same URL is not necessary. In many cases, this status points to issues with content quality, relevance, or value rather than a simple technical error.
Understanding Google Indexing and Search Console
Before we get into solutions, it helps to understand the indexing process and the tool that reports on it.
What Is Google Search Console?
Google Search Console is a free toolset from Google that shows you what the search engine sees when it visits your website. It includes data on search performance, technical updates, index coverage, and crawl stats. One of its most useful features is the breakdown of index status across your pages.
How the Indexing Process Works
The process starts with Google's web crawlers, also known as spiders, visiting a URL on your site. Google discovers those URLs through your site structure, your sitemap, RSS feeds, and links from other websites. Once the crawl is complete, the data is processed, and if the page is found useful, it is added to Google's index. Only then can the page surface in search results and pull in users organically.
Understanding Index Status in the Page Indexing Report
Indexed
This is the desired condition for most web pages. Google has crawled the page and added it to the search index, so it is eligible to appear in Google search results.
Indexed, Not Submitted in Sitemap
Google has indexed a page you did not include in your sitemap. Including every page is not required, but submitting every important page is a best practice worth following.
Crawled - Currently Not Indexed
The problem state we are addressing here. Google's spiders have crawled these affected pages, but nothing was added to the search index. Google knows they exist and has chosen to leave them out.
Discovered - Currently Not Indexed
A related status that is often confused with the one above. Here Google knows the URL exists but has not crawled it yet, which usually points to site structure and crawl access rather than content quality.
Why Your Pages Are "Crawled - Currently Not Indexed"
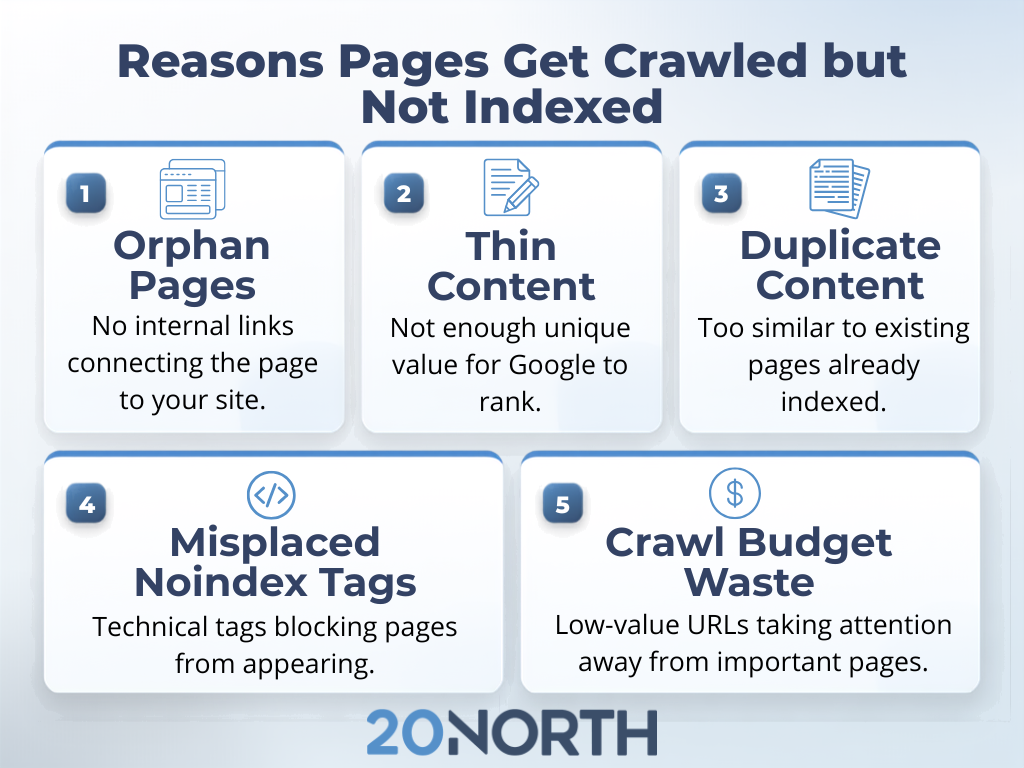
Orphan Pages and Weak Internal Linking
An orphan page exists on your website but is not connected to the rest of your site through any internal link. Google's crawlers have a hard time discovering these pages and an even harder time judging their relevance, which often results in non-indexing.
The fix. Build an internal linking plan. Internal links give users a clear path through your site and give Google's crawlers a bridge between related pages. Every important page should sit no more than three clicks from your homepage and should be linked from a relevant category or blog content.
Thin Content and Duplicate Content
Both quality and uniqueness matter. Google works to provide the best user experience, so pages with thin content that offer little value or duplicate content that repeats what already exists elsewhere tend to be skipped during the indexing process.
The fix. For thin content, focus on content quality. Provide original content that demonstrates your expertise and answers user intent. That could mean rewriting weak sections, adding an interactive section such as a calculator or comparison table, or expanding high-intent pages with unique value a competitor cannot copy. For duplicate content, you have two options. Remove one of the pages entirely, or place a canonical tag on the URL you want showing in search results.
Noindex Tags
A noindex tag in your page's HTML tells Google not to index that URL. The tag is useful for pages you deliberately want out of search results, but a misplaced one will quietly keep an important page out of Google's index no matter how good the content is.
The fix. Audit your HTML and remove the tag from any page that should be indexed. Our e-commerce SEO audit guide walks through how to catch these at scale.
Crawl Budget Waste
A crawl budget refers to the number of pages Google's crawler is able to crawl on your site within a given timeframe. Large sites with thousands of low-value URLs, such as filtered product pages or parameter URLs, can burn through that budget before Google reaches the pages that matter.
The fix. Cut the number of unimportant pages. Set low-value URLs to noindex, consolidate near-duplicate product pages, and clean up parameter URLs so crawlers spend their time on important pages.
Search Intent Mismatch
Sometimes the page is well written but does not match what users are actually searching for. Google already has helpful content covering that query and sees no reason to add another version.
The fix. Rework the existing page around the search intent behind your target keyword. Our Shopify SEO checklist covers how to map intent to page type on an e-commerce site.
How to Fix "Crawled - Currently Not Indexed" Status
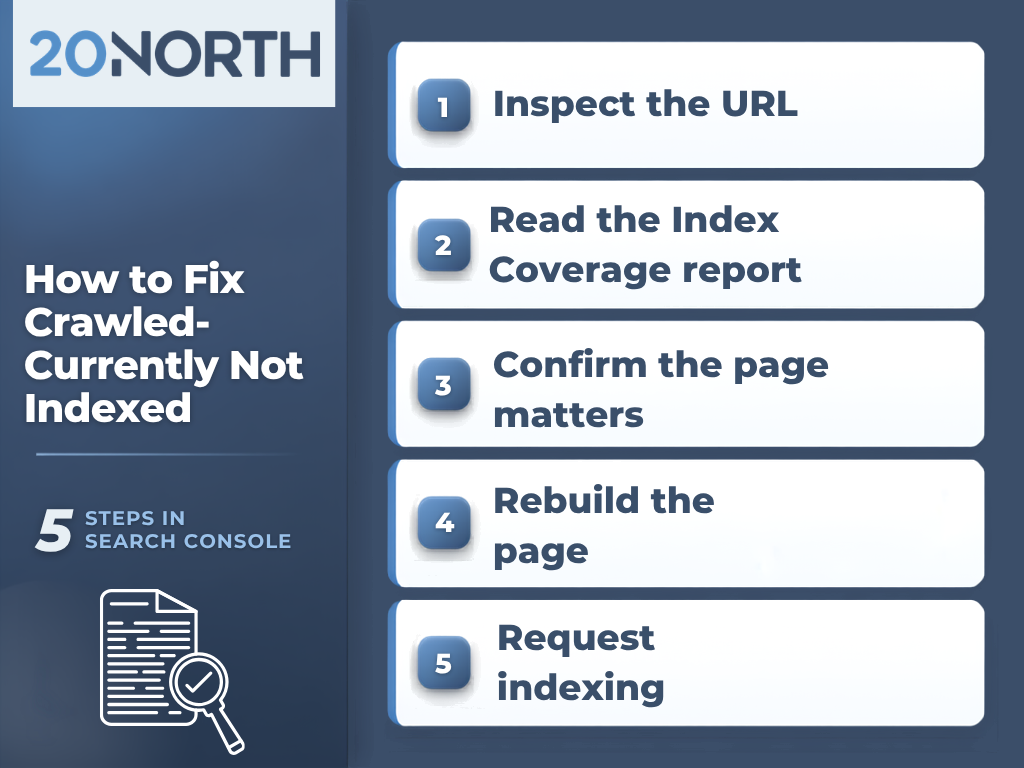
Use the URL Inspection Tool
The simplest way to check and push a single URL is the URL Inspection Tool at the top of GSC. It shows how Google's search engine sees the page and lets you request indexing manually. Keep in mind that requesting indexing on a thin page will not override a quality judgment.
Review the Index Coverage Report
The Index Coverage report lists every page Google has tried to crawl but has not added to the search index, along with the reason for each. This is the fastest way for a site owner to see all affected pages in one place and spot patterns across a section of the site.
Strengthen the Page Before You Resubmit
Improve the content first, then request indexing. Add unique content, tighten the internal linking pointing to the page, confirm the canonical tag points where it should, and add schema markup so Google understands the page context. This matters more than ever now that AI-driven search surfaces pull from Google's index to build answers.
Automate Indexing on Shopify
Because we come across this issue constantly, we built a Shopify Instant Indexer app. When you publish new pages on your Shopify store, the app submits them to Google automatically without manual requests in GSC.
Which Pages Should Be Indexed
Not every URL in this report needs fixing. Paginated pages, filtered views, and internal search results often belong outside the index by design. Before spending time making changes, confirm that the affected pages are ones you actually want to appear in Google Search. In some cases, Google is correctly leaving lower-value URLs out of the index, which helps preserve crawl resources for the pages that provide the most value to your business.
How 20North Can Help
Resolving indexing issues requires more than requesting Google to crawl a page again. Identifying why a page is not being indexed, improving the factors limiting visibility, and monitoring results requires a combination of technical SEO, content optimization, and ongoing analysis. \
These steps are straightforward in theory, but implementing them across a large site is a different story. 20North is a full-service digital marketing agency in Atlanta specializing in SEO, AEO, web development, paid media, conversion rate optimization, and email marketing. Our team helps businesses identify the root causes behind indexing issues, optimize the pages that matter most, and implement SEO improvements that increase visibility in search results.
Get in touch with us today and let's get your pages into Google's index!